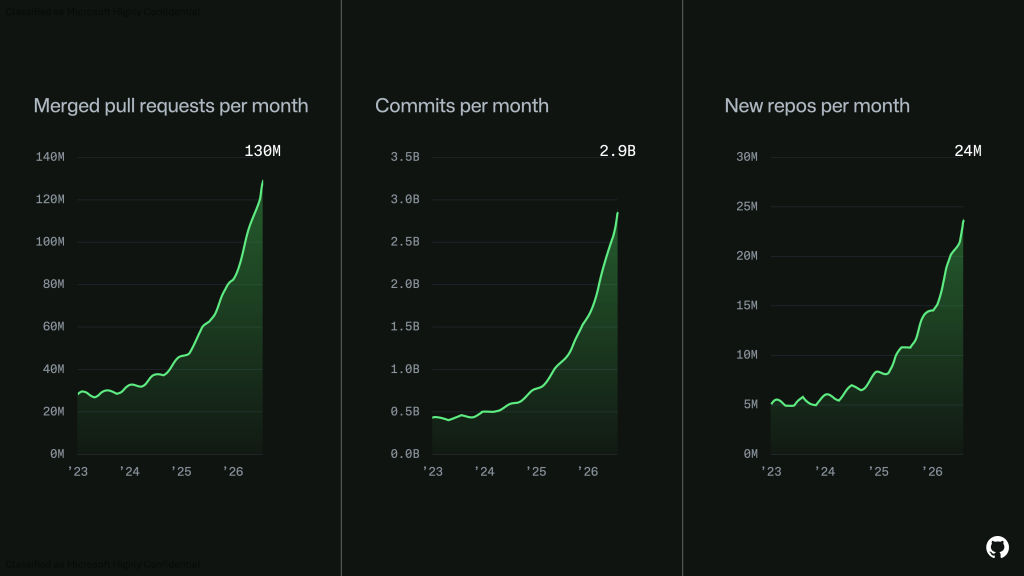
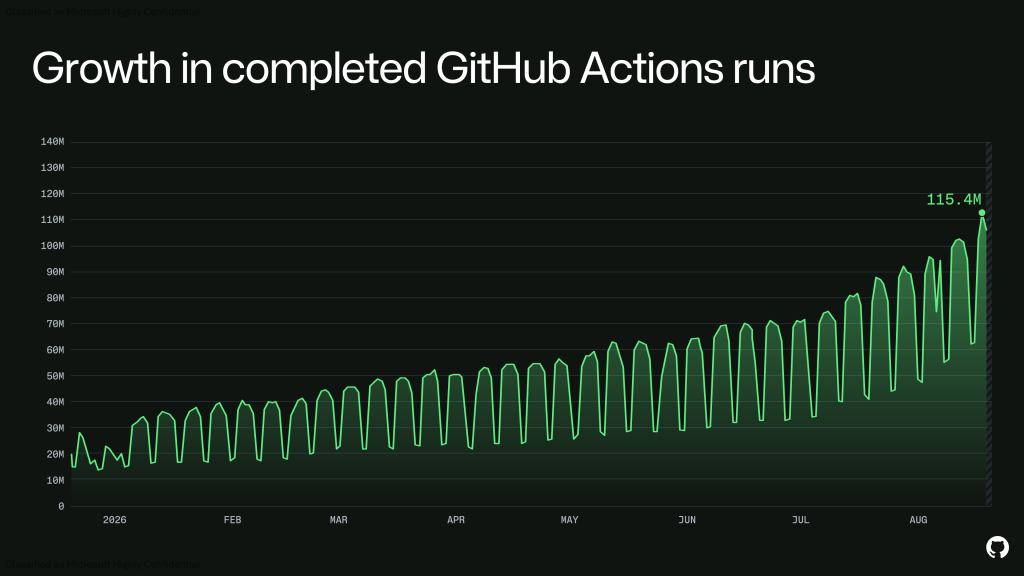
 What we have done and what comes next As part of the reliability commitments we made earlier this year, we have focused on three priorities: adding capacity, improving efficiency, and removing architectural bottlenecks. We have since added more than 3 million CPU cores, 120 petabytes of high-speed storage, and significant network capacity. We installed as much hardware as available power allowed in our existing data centers while accelerating our migration to Azure. Today, Azure serves roughly 58% of GitHub’s platform load and half of all Git operations, up from 12% of platform load in May. This expanded footprint has also supported the growth in GitHub Actions job runs shown below.
 Azure’s infrastructure and capacity have also accelerated our work to scale the largest monorepos. Our next milestone is an architecture that scales read capacity linearly with the number of readers, enabling unlimited read operations. We will roll it out gradually, beginning with the largest monorepos.
 Scale is not our only challenge. As the pace and complexity of change increased, our existing operational practices did not keep up. We have redirected teams and resources toward availability and invested in stronger testing, safer rollouts, better observability, and more effective alerting. We have made progress, but this work is not complete. In addition, we are also isolating critical systems and removing shared dependencies between them. This work is designed to reduce the likelihood of an outage and limit its impact when one occurs. We learn from every outage and add new work to our availability workstream. The August 6 and August 17 incidents led to two immediate changes. First, we are applying consistent retry limits, retry budgets, and variable timeouts across service-to-service interactions to prevent retry storms and cascading load. Second, we are reviewing lower-priority CPU and memory alerts to identify components that could fail during sudden traffic spikes. Our commitment to high availability isn’t just a technical promise. The developer community depends on GitHub to build, ship, and operate their work. That is only possible if you can rely on us, and on August 17, you couldn’t. It is our responsibility to fix that. We’ll earn your trust through the scaling and reliability of the platform. The post The August 17 outage, and the work ahead appeared first on The GitHub Blog.
Source: https://github.blog/news-insights/compa ... ork-ahead/